Think of this as the morning paper for the AI world. Every morning a script visits AI sites around the world, gathers what is new, and puts each item on a card of its own.
There are five kinds — papers (research reports), models (an AI’s brain files), GitHub (a warehouse for program code), newly out (company announcements) and talk (articles, forums, podcasts). Pick one in the menu to see only that kind, with a short note on what it is. Click a card’s title to open the original.
What turned up in the last three days — collected by machine, published by hand.
What gets picked here ends up in What I took apart →
Collected 2026-10-15 23:01 UTC · 44 kept from 418
Picked so every source keeps a slot. Go into a category and that category is complete.
Pythonai-agentSource GitHub
onehumanbeing/esp32-iphone-agent2.4k stars322 forks
MITPythonpushed today
Location, estimated · United States
What we saw
“Let an AI model use a real iPhone with a $7 ESP32: AirPlay eyes, USB HID hands, any OpenAI-compatible vision model. No Mac, no …”
Published 2026-10-11
Fetched 2026-10-13 23:01 UTC · 56e3d501b6411969
What the account wrote — New York
Torn from — the README
Source Hacker News
Gemini 4 Argon1.4k points1.0k comments
states limits3.3k words
What we saw
“See also: <i>Gemini 4 Argon for Robotics</i> - <a href="https://news.ycombinator.com/item?id=50074869">https:&#x…”
They claim — Argon ties for #1 on CWE-Bench (68%) for vulnerability remediation, is our most resilient model against indirect prompt injections, and is expanding to hundreds of additional Fairwind Pro…
Published 2026-10-13
Fetched 2026-10-13 23:01 UTC · 807961f7ded6073d
Torn from — the page itself
Thread ↗ Source Hacker News
Redesigning source control at Anthropic863 points962 comments
states limits3.8k words
What we saw
This source gives a title and a link, nothing to quote.
They claim — The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB.
Published 2026-10-13
Fetched 2026-10-13 23:01 UTC · 014a3fa5c3e00ad1
Torn from — the page itself
Thread ↗ JavaScriptbotSource GitHub
Fei2411/DeepSeek-Bot2.0k stars192 forks
Apache-2.0JavaScriptpushed today
Location, estimated · Not stated
What we saw
“A team of long-lived bots for DeepSeek Harness, with main bots, bot-to-bot messages and group chats.”
Published 2026-10-07
Fetched 2026-10-13 23:01 UTC · f95ff77c0b1f0b50
What the account wrote — The account left it blank
Torn from — the README
Rust3d-modelingSource GitHub
bherbruck/solidcraft2.7k stars281 forks
Apache-2.0Rustpushed today
Location, estimated · Not stated
What we saw
“SolidCraft: an open-source parametric 3D CAD application built in pure Rust. Desktop, web, and automation through MCP.”
They claim — A Raspberry Pi 4 case from an empty design: a sketch dimensioned with the board's parameters, extrude, fillet, shell, the rim rounded in one pick, an M2.5 standoff patterned on the 58 × …
Published 2026-10-07
Fetched 2026-10-14 23:02 UTC · edd2f0662ef18e33
What the account wrote — The account left it blank
Torn from — the README
text-generationtransformersSource Hugging Face
LiquidAI/LFM2.5-24B-A2B386 likes6.3k downloads
otherbuilt on LFM2.5-24B-A2B-Base
What we saw
This source gives a title and a link, nothing to quote.
They claim — Best-in-class agent: Competitive with Qwen3.6-35B-A3B, a model with ~50% more total and active parameters, on agentic and tool-use tasks, scoring 48.09 on LiveClaw versus 38.19.
Published 2026-10-12
Fetched 2026-10-13 23:01 UTC · c579ed3cfe2e10ec
Torn from — the model card
image-text-to-texttransformersSource Hugging Face
openbmb/MiniCPM-V-4.7-35B-A3B790 likes9.3k downloads
apache-2.0
What we saw
This source gives a title and a link, nothing to quote.
They claim — With our Lookahead Expert Scheduling (LES) technique introduced alongside MiniCPM-V 4.7, combined with fine-grained layer-wise quantization and DSpark speculative sampling integration, Mi…
Published 2026-10-07
Fetched 2026-10-13 23:01 UTC · 5ca3d9ef5e7bf155
Torn from — the model card
text-to-speechsafetensorsSource Hugging Face
fishaudio/drama-3467 likes4.0k downloads
other
What we saw
This source gives a title and a link, nothing to quote.
They claim — A single stream gets its first audio in under 100 ms.
Published 2026-10-01
Fetched 2026-10-14 23:02 UTC · ea49f1b15998335c
Torn from — the model card
Source Hacker News
Goai-agentSource GitHub
jiwoochris/artex-global1.5k stars1.8k forks
AGPL-3.0Gopushed today
Location, estimated · Korea
What we saw
“ARTEX 한국어판 · AI 자율 침투 테스트 프레임워크(upstream: Autumn-27/ARTEX, AGPL-3.0)”
They claim — A cheaper, smaller model (for example gpt-4o-mini), by contrast, let the report fall back to the original language.
Published 2026-10-03
Fetched 2026-10-13 23:01 UTC · ba08d341154c8561
What the account wrote — South Korea
Torn from — the README
zero-shot-classificationtransformersSource Hugging Face
vllm-sr/d3197 likes2.7k downloads
apache-2.0built on Qwen3.8-27B
What we saw
This source gives a title and a link, nothing to quote.
They claim — Speed: text requests take a median of 54.4 ms, requests with an image a median of 290 ms, and requests with a 10-second video a median of 500 ms, on one AMD Instinct MI325X, one request a…
Published 2026-10-10
Fetched 2026-10-13 23:01 UTC · 01560164c36d18da
Torn from — the model card
image-text-to-texttransformersSource Hugging Face
openbmb/MiniCPM-V-4.7-1B360 likes5.3k downloads
apache-2.0
What we saw
This source gives a title and a link, nothing to quote.
They claim — The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs.
Published 2026-10-06
Fetched 2026-10-13 23:01 UTC · d1276768476a030a
Torn from — the model card
text-classificationtransformersSource Hugging Face
autotrust/JEV-35B-NVFP4306 likes33k downloads
apache-2.0built on JEV-35B
What we saw
This source gives a title and a link, nothing to quote.
They claim — Speed: the same latency as bf16 on one B200 for single requests; the gain is memory (one 32–48 GB GPU is enough).
Published 2026-10-11
Fetched 2026-10-13 23:01 UTC · b0be99502d578ee1
Torn from — the model card
Source MIT News AINew
Source MIT News AINew
AI model decodes the language cells use to communicateOct 15
no limits stated851 words
What we saw
“A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineerin…”
They claim — 8, could accelerate stem cell engineering for regenerative medicine and improve the creation of organoids — miniature, 3D models that mimic real organs — for studying disease mechanis…
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · d4cf67508af122dc
Torn from — the listing only (the original would not open)
Source Hugging Face BlogNew
Granite Switch 4.1: Chat, Decisions, and Speech from One EndpointOct 15
no limits stated829 words
What we saw
This source gives a title and a link, nothing to quote.
They claim — In a “Race” between Granite-Switch-4.1-30B (frozen base Granite + 4 specialized aLoRAs) and Jev-27B (frozen base Qwen model + 1 generic decision LoRA), Granite-Switch-4.1-30B was able…
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 58422c23d696b293
Torn from — the page itself
Source TechCrunch AINew
Meta launches an open-weight AI model that runs on MacsOct 15
no limits stated584 words
What we saw
“Meta and Apple have teamed up for the launch of the social media giant's newest model, Muse Spark Open, which will run locally …”
They claim — Get your pass and bring someone with you at 50% off.
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 289086d789839bfb
Torn from — the page itself
Source OpenAINew
Bringing GPT-Rosalind to academic research labsOct 15
What we saw
“Introducing the Rosalind Academic Plan, offering eligible academic labs sponsored access to GPT-Rosalind and tools to advance l…”
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 6d9d156035ebcbb1
Torn from — the listing only (the original would not open)
Source r/ClaudeAINew
Source AWS ML BlogNew
Meta’s Muse Spark Open now available in Amazon SageMaker JumpStartOct 15
no limits stated1.9k words
What we saw
“Muse Spark Open, Meta's coding-optimized open-weight model, is now available in Amazon SageMaker JumpStart. Deploy it to a Sage…”
They claim — p6-b300.48xlarge modelid = "meta-vlm-muse-spark-open-816b-a42b-nvfp4" jumpstartconfig = JumpStartConfig( modelid=modelid, accepteula=True, # Confirms that you accept Meta's license terms …
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · bfa295e4cfe2ab36
Torn from — the listing only (the original would not open)
Source r/ClaudeAINew
Clod Update: Claude promoted him after 1 million viewsOct 15
states limits238 words
What we saw
“So somehow my original post about Clod, the random rock Claude hired, has reached over a million views lmao. I've been read…”
They claim — Clod's performance review: Attendance: 100% Complaints: 0 Mistakes: 0 Actual work completed: 0 Despite that last part, Claude still thinks he's doing an excellent job.
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 2208f529c6e9dc12
Torn from — the listing only (the original would not open)
Thread ↗ Source AWS ML BlogNew
Trust in Depth: Giving agents more autonomy without losing controlOct 15
states limits2.7k words
What we saw
“Enterprise leaders want AI agents to take on more work but don't fully trust them to act correctly every time. Trust in Depth i…”
They claim — AWS has run automated reasoning in production for more than a decade, from Identity and Access Management (IAM) at more than 2.1 billion requests per second to critical systems like the A…
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 5b5b08e75438e6a6
Torn from — the listing only (the original would not open)
Source Practical AINew
Education is Failing our Students in this AI-Driven WorldOct 15
no limits stated200 words
What we saw
“Schools and universities are failing to adapt to our modern world, in which AI is becoming increasingly pervasive in all aspect…”
They claim — Prior Webinars from our partner Prediction GuardMidwest AI Summit 2026Chris’s new book The Art of Swarming will be published soon, written to be the seminal foundational book for the fl…
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · f994fc8f0a15602a
Torn from — the listing only (the original would not open)
Source TWIML AINew
Your Ranking Model Is Optimizing the Wrong Thing with Zoe Weil - #780Oct 15
no limits stated145 words
What we saw
“In this episode, Zoe Weil, co-founder and CEO of Sequen, joins us to discuss how ranking systems can use live behavioral signal…”
Published 2026-10-15
Fetched 2026-10-15 23:01 UTC · 1a30cc7dc26c8f7c
Torn from — the listing only (the original would not open)
image-to-imagediffusersSource Hugging Face
black-forest-labs/flux-3-image-klein201 likes3.2k downloads
other
What we saw
This source gives a title and a link, nothing to quote.
Published 2026-10-13
Fetched 2026-10-15 23:01 UTC · 722181fb8cc2c805
Torn from — the listing only (the original would not open)
Pythonagent-skillSource GitHub
Arekejoker/qwen21-nsfw-pose-skill2.0k stars414 forks
no licensePythonpushed today
Location, estimated · Not stated
What we saw
“Qwen-Image 2.1 NSFW/姿势出图 skill:作者级提示词配方 + NSFW LoRA + 136 姿势 VNCCS 人偶控制;适用 Claude C…”
They claim — 底模为 Qwen-Image 2.1 int8 套件,模型文件合计约 16GB(diffusion 6.8GB / text encoder 8.7GB / VAE 0.6GB),LoRA 各自 ≤608MB。
Published 2026-10-13
Fetched 2026-10-15 23:01 UTC · 6dfee4bf4e7948d1
What the account wrote — The account left it blank
Torn from — the README
 Source HF Daily Papers
Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards74 upvotes1 comments
6 authorsno limits stated
What we saw
“Long-horizon agents have drawn growing attention for their ability to work autonomously -- from hours to days -- on economicall…”
They claim — Training with this recipe yields Tev-27B, which achieves substantial gains on the Agents' Last Exam computing and math sciences domains (ALE-CM), matching GPT-6 Astra and Claude Opus 5 at…
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 1455000d21b11d5b
Torn from — the abstract
Thread ↗  Source HF Daily Papers
AesCode: Aesthetic Code Generation with Decoupled Cross-Modal Rewards79 upvotes1 comments
16 authorsstates limits
What we saw
“Generating information-rich visual artifacts such as slides, posters, and dashboards as code is appealing because the outputs a…”
They claim — Relative to same-scale Qwen3-VL baselines given the same references, AesCode-8B and AesCode-32B improve visual quality by 31.1 and 22.4 percentage points, reaching scores comparable to th…
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 97d77105361eeafc
Torn from — the abstract
Thread ↗ 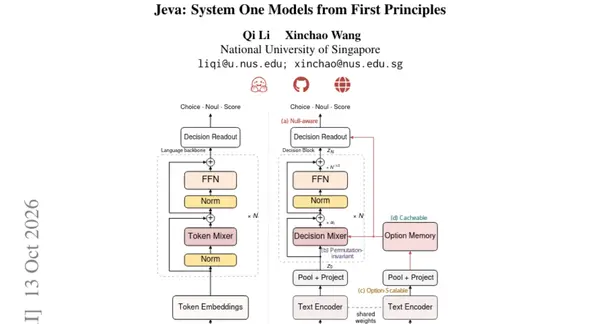 Source HF Daily Papers
Jeva: System One Models from First Principles264 upvotes1 comments
2 authorsstates limits
What we saw
“System one models enable direct, low-latency decision-making. Yet recent practice of predicting an answer from serialized text …”
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 4f31453ef992a999
Torn from — the abstract
Thread ↗  Source HF Daily Papers
GreenWAM: A World Foundation Model for Robotics82 upvotes1 comments
5 authorsno limits stated
What we saw
“A robot needs a world model that predicts how its actions will change the scene and a policy that chooses those actions. Models…”
They claim — We present GreenWAM, a world foundation model for robotics, together with the recipe that produces it: (1) a shared anatomical action space that describes 20 robot families, from bimanual…
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · c62ac72a3957f563
Torn from — the abstract
Thread ↗  Source HF Daily Papers
Agent-Reflex: Teaching Language Agents to Act Reflectively192 upvotes1 comments
12 authorsno limits stated
What we saw
“Large language models have evolved from single-turn chatbots into interactive agents capable of long-horizon reasoning. In real…”
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 9aa68b006650bde0
Torn from — the abstract
Thread ↗  Source HF Daily Papers
Urbex: Agentic Spatial Grounding for City-Scale 3D Scenes109 upvotes1 comments
8 authorsno limits stated
What we saw
“City-scale 3D grounding is commonly formulated as candidate ranking, which requires precomputed instance proposals and becomes …”
They claim — Experiments show that Urbex achieves the best Hit@1 and IoU on CityRefer, supports candidate-free grounding without ground-truth boxes, and is substantially faster than the strongest city…
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 0bfa851286be4403
Torn from — the abstract
Thread ↗  Source HF Daily Papers
VideoJev: System One Model for Video Understanding and Interaction191 upvotes1 comments
18 authorsno limits stated
What we saw
“Visual agents must turn video observations into timely decisions to track progress and choose what to do next. Building on the …”
They claim — Across three temporal grounding benchmarks, VideoJev-4B and VideoJev-35B-A3B improve mean mIoU over their backbones by 6.7 and 10.8 points, respectively, with measured inference speedups …
Published 2026-10-12
Fetched 2026-10-14 23:02 UTC · 1de37de22c03c2cf
Torn from — the abstract
Thread ↗ PythonSource GitHub
academa-labs/manimgx1.4k stars99 forks
MITPythonpushed today
Location, estimated · United States
What we saw
“The animation engine for agents: blazingly fast math and 3D videos with Manim's Python API, on a Rust GPU core.”
They claim — Across five scenes at 1080p60 on an Apple M4 Pro, ManimGX is 90.6× faster than ManimCE, 11.5× faster than ManimGL, and 18.7× faster than Blender Workbench, from launch to finished MP4.
Published 2026-10-05
Fetched 2026-10-15 23:01 UTC · f52bdc10842e8288
What the account wrote — United States of America
Torn from — the README
Nothing on this page matches what you picked.
Papers, repos, models, blogs, Reddit and podcasts — once a day, by machine. Everything collected gets taken apart once — the README, the abstract, the model card — and what that turns up is kept for good, whether or not it becomes a card. Titles and links go to the original; nothing is reproduced here.
The grey line on each card is what the teardown found, not what the source advertises: the licence, the last commit, the model it was built on, whether the paper states its own limits. Open “What we saw” to check what was read to get it. Where it says listing only, the original could not be read — some sites refuse us, and we do not pretend otherwise.
A line in quotation marks is a sentence lifted from the source itself — their number, not a measurement of ours. We copy it and leave it unchecked; that is the point of quoting it.
Topics are assigned by matching words in the original title, quote and tags against a fixed list — no model reads the card. Some cards match nothing and carry no topic at all; pick a topic and those drop out. Source and topic narrow together.
Each card keeps the sentence we actually read at the moment we read it, plus a fingerprint of the response we received. That sentence — not the whole page — is what we can still stand behind if the original later changes or disappears.
Guessed from one free-text field the account filled in itself, and half of them leave it empty. Shown as its own value rather than hidden.