05

Papers

A paper is a research report: “we tried this, and here is what happened.” These come from arXiv — an open board where anyone can post a paper before it is reviewed — and from the list of papers Hugging Face picks out every day.

Many have not been checked by other experts yet, so read them as new claims rather than settled facts. Upvotes and comments are how many people voted for or commented on the paper on that daily list.

What turned up in the last three days — collected by machine, published by hand.

What gets picked here ends up in What I took apart →

Collected 2026-10-15 23:01 UTC · 44 kept from 418

Source HF Daily Papers
Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards

74 upvotes1 comments

6 authorsno limits stated

What we saw

“Long-horizon agents have drawn growing attention for their ability to work autonomously -- from hours to days -- on economicall…”

They claim — Training with this recipe yields Tev-27B, which achieves substantial gains on the Agents' Last Exam computing and math sciences domains (ALE-CM), matching GPT-6 Astra and Claude Opus 5 at…

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 1455000d21b11d5b

Torn from — the abstract

Thread ↗
Source HF Daily Papers
AesCode: Aesthetic Code Generation with Decoupled Cross-Modal Rewards

79 upvotes1 comments

16 authorsstates limits

What we saw

“Generating information-rich visual artifacts such as slides, posters, and dashboards as code is appealing because the outputs a…”

They claim — Relative to same-scale Qwen3-VL baselines given the same references, AesCode-8B and AesCode-32B improve visual quality by 31.1 and 22.4 percentage points, reaching scores comparable to th…

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 97d77105361eeafc

Torn from — the abstract

Thread ↗
Source HF Daily Papers
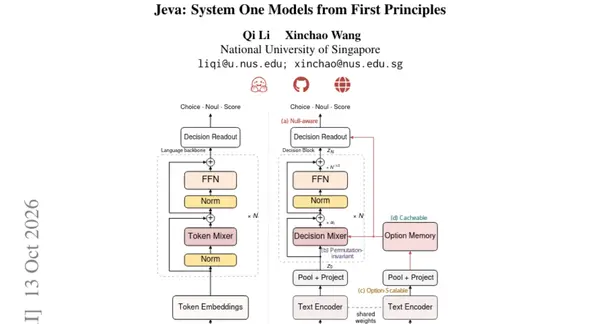
Jeva: System One Models from First Principles

264 upvotes1 comments

2 authorsstates limits

What we saw

“System one models enable direct, low-latency decision-making. Yet recent practice of predicting an answer from serialized text …”

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 4f31453ef992a999

Torn from — the abstract

Thread ↗
Source HF Daily Papers
GreenWAM: A World Foundation Model for Robotics

82 upvotes1 comments

5 authorsno limits stated

What we saw

“A robot needs a world model that predicts how its actions will change the scene and a policy that chooses those actions. Models…”

They claim — We present GreenWAM, a world foundation model for robotics, together with the recipe that produces it: (1) a shared anatomical action space that describes 20 robot families, from bimanual…

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · c62ac72a3957f563

Torn from — the abstract

Thread ↗
Source HF Daily Papers
Agent-Reflex: Teaching Language Agents to Act Reflectively

192 upvotes1 comments

12 authorsno limits stated

What we saw

“Large language models have evolved from single-turn chatbots into interactive agents capable of long-horizon reasoning. In real…”

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 9aa68b006650bde0

Torn from — the abstract

Thread ↗
Source HF Daily Papers
Urbex: Agentic Spatial Grounding for City-Scale 3D Scenes

109 upvotes1 comments

8 authorsno limits stated

What we saw

“City-scale 3D grounding is commonly formulated as candidate ranking, which requires precomputed instance proposals and becomes …”

They claim — Experiments show that Urbex achieves the best Hit@1 and IoU on CityRefer, supports candidate-free grounding without ground-truth boxes, and is substantially faster than the strongest city…

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 0bfa851286be4403

Torn from — the abstract

Thread ↗
Source HF Daily Papers
VideoJev: System One Model for Video Understanding and Interaction

191 upvotes1 comments

18 authorsno limits stated

What we saw

“Visual agents must turn video observations into timely decisions to track progress and choose what to do next. Building on the …”

They claim — Across three temporal grounding benchmarks, VideoJev-4B and VideoJev-35B-A3B improve mean mIoU over their backbones by 6.7 and 10.8 points, respectively, with measured inference speedups …

Published 2026-10-12

Fetched 2026-10-14 23:02 UTC · 1de37de22c03c2cf

Torn from — the abstract

Thread ↗
Source HF Daily Papers
AgentSWE: Can Coding Agents Build the Agent You Actually Want?

201 upvotes1 comments

5 authorsno limits stated

What we saw

“As the production of software passes into the hands of software itself, coding agents are increasingly commissioned to build ag…”

Published 2026-10-08

Fetched 2026-10-13 23:01 UTC · cc4e0966638e62f2

Torn from — the abstract

Thread ↗
Source HF Daily Papers
Scaling Agentic Data for Long-Horizon Terminal Intelligence

133 upvotes1 comments

9 authorsno limits stated

What we saw

“Terminal agents are moving beyond local operations toward completing real-world professional tasks. Short trajectories can demo…”

They claim — We achieve substantial performance gains on all 12 benchmarks spanning coding-agent tasks, agentic tasks in real-world production settings, and general reasoning.

Published 2026-10-08

Fetched 2026-10-13 23:01 UTC · 5ca7f2d4afa12535

Torn from — the abstract

Thread ↗
Source HF Daily Papers
Thinking Inertia: LLMs Keep Thinking When Told Not To

215 upvotes2 comments

5 authorsstates limits

What we saw

“Large Language Models (LLMs) increasingly ship with explicit "thinking modes", yet their counterpart, "no-thinking", has receiv…”

Published 2026-10-07

Fetched 2026-10-13 23:01 UTC · 611e236bfc72dfb4

Torn from — the abstract

Thread ↗
Source HF Daily Papers
VIS-Ground: Video Interactive Storytelling with Contextual Grounding

78 upvotes1 comments

13 authorsno limits stated

What we saw

“Video interactive storytelling enables viewers to actively steer how a video unfolds. However, once we allow viewers to interve…”

They claim — Across three video generation backbones, VIS-Ground consistently achieves the highest overall composite score, reaching an average absolute improvement of 10.3 points over the strongest p…

Published 2026-10-06

Fetched 2026-10-13 23:01 UTC · 00f2425bd978c006

Torn from — the abstract

Thread ↗
Source HF Daily Papers
GroundingPI: A Grounding Foundation Model towards Physical Intelligence with Visual Primitives

247 upvotes1 comments

26 authorsno limits stated

What we saw

“Precise grounding matters. It specifies which object is the target and where that object is, even in clutter and for tiny objec…”

They claim — Against 44 baselines across 34 grounding benchmarks spanning 11 perceptual capabilities, GroundingPI establishes a new state of the art, averaging 73.68%, above the larger GPT-6 Astra (71…

Published 2026-09-29

Fetched 2026-10-13 23:01 UTC · 0c3dcf5d1875e3cc

Torn from — the abstract

Thread ↗

Papers, repos, models, blogs, Reddit and podcasts — once a day, by machine. Everything collected gets taken apart once — the README, the abstract, the model card — and what that turns up is kept for good, whether or not it becomes a card. Titles and links go to the original; nothing is reproduced here.

The grey line on each card is what the teardown found, not what the source advertises: the licence, the last commit, the model it was built on, whether the paper states its own limits. Open “What we saw” to check what was read to get it. Where it says listing only, the original could not be read — some sites refuse us, and we do not pretend otherwise.

A line in quotation marks is a sentence lifted from the source itself — their number, not a measurement of ours. We copy it and leave it unchecked; that is the point of quoting it.

Topics are assigned by matching words in the original title, quote and tags against a fixed list — no model reads the card. Some cards match nothing and carry no topic at all; pick a topic and those drop out. Source and topic narrow together.

Each card keeps the sentence we actually read at the moment we read it, plus a fingerprint of the response we received. That sentence — not the whole page — is what we can still stand behind if the original later changes or disappears.