05

논문

논문은 연구자들이 「이런 걸 해 봤더니 이렇게 나왔다」를 적어 공개한 실험 보고서입니다. 여기 모인 것은 arXiv(아카이브 — 누구나 논문을 먼저 올릴 수 있는 공개 게시판)와, Hugging Face(허깅페이스)가 매일 골라 소개하는 논문 목록에서 왔습니다.

다른 전문가의 검토를 아직 거치지 않은 것이 많습니다. 「확정된 사실」이 아니라 「새로 나온 주장」으로 읽으면 됩니다. 카드의 「추천」은 그 목록에서 사람들이 눌러 준 추천 수, 「댓글」은 달린 댓글 수입니다.

사흘 안에 눈에 띈 것. 모으는 건 기계가, 올리는 건 내가 고른다.

여기서 고른 것을 뜯는다 → 뜯어본 생각

2026-10-15 23:01 UTC 수집 · 418건 중 44건

출처 HF Daily Papers
긴 시간 스스로 일하는 AI를 위한 보상 방식 개발

74 추천1 댓글

저자 6명한계 언급 없음

우리가 본 것

원제 — Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards

“Long-horizon agents have drawn growing attention for their ability to work autonomously -- from hours to days -- on economicall…”

대상 주장 — Training with this recipe yields Tev-27B, which achieves substantial gains on the Agents' Last Exam computing and math sciences domains (ALE-CM), matching GPT-6 Astra and Claude Opus 5 at…

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 1455000d21b11d5b

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
코드 방식으로 시각 자료를 만드는 AesCode 기술

79 추천1 댓글

저자 16명한계 적음

우리가 본 것

원제 — AesCode: Aesthetic Code Generation with Decoupled Cross-Modal Rewards

“Generating information-rich visual artifacts such as slides, posters, and dashboards as code is appealing because the outputs a…”

대상 주장 — Relative to same-scale Qwen3-VL baselines given the same references, AesCode-8B and AesCode-32B improve visual quality by 31.1 and 22.4 percentage points, reaching scores comparable to th…

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 97d77105361eeafc

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
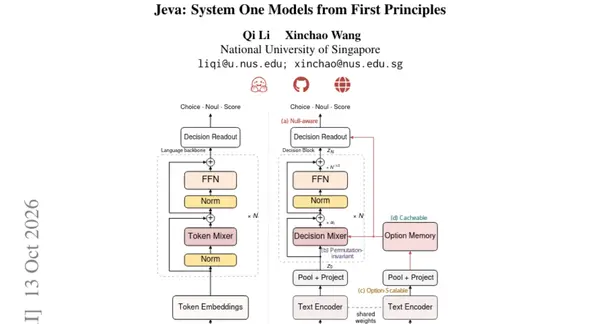
직접 판단하고 빠르게 결정하는 System One 모델

264 추천1 댓글

저자 2명한계 적음

우리가 본 것

원제 — Jeva: System One Models from First Principles

“System one models enable direct, low-latency decision-making. Yet recent practice of predicting an answer from serialized text …”

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 4f31453ef992a999

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
로봇의 동작과 변화를 예측하는 모델 GreenWAM

82 추천1 댓글

저자 5명한계 언급 없음

우리가 본 것

원제 — GreenWAM: A World Foundation Model for Robotics

“A robot needs a world model that predicts how its actions will change the scene and a policy that chooses those actions. Models…”

대상 주장 — We present GreenWAM, a world foundation model for robotics, together with the recipe that produces it: (1) a shared anatomical action space that describes 20 robot families, from bimanual…

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · c62ac72a3957f563

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
언어 에이전트가 스스로 생각하며 행동하도록 가르치는 기술

192 추천1 댓글

저자 12명한계 언급 없음

우리가 본 것

원제 — Agent-Reflex: Teaching Language Agents to Act Reflectively

“Large language models have evolved from single-turn chatbots into interactive agents capable of long-horizon reasoning. In real…”

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 9aa68b006650bde0

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
도시 규모의 3D 장면에서 사물을 찾아내는 기술

109 추천1 댓글

저자 8명한계 언급 없음

우리가 본 것

원제 — Urbex: Agentic Spatial Grounding for City-Scale 3D Scenes

“City-scale 3D grounding is commonly formulated as candidate ranking, which requires precomputed instance proposals and becomes …”

대상 주장 — Experiments show that Urbex achieves the best Hit@1 and IoU on CityRefer, supports candidate-free grounding without ground-truth boxes, and is substantially faster than the strongest city…

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 0bfa851286be4403

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
비디오 이해와 상호작용을 위한 VideoJev 시스템

191 추천1 댓글

저자 18명한계 언급 없음

우리가 본 것

원제 — VideoJev: System One Model for Video Understanding and Interaction

“Visual agents must turn video observations into timely decisions to track progress and choose what to do next. Building on the …”

대상 주장 — Across three temporal grounding benchmarks, VideoJev-4B and VideoJev-35B-A3B improve mean mIoU over their backbones by 6.7 and 10.8 points, respectively, with measured inference speedups …

나온 때 2026-10-12

가져온 때 2026-10-14 23:02 UTC · 1de37de22c03c2cf

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
코딩 에이전트의 에이전트 제작 가능 여부 연구

201 추천1 댓글

저자 5명한계 언급 없음

우리가 본 것

원제 — AgentSWE: Can Coding Agents Build the Agent You Actually Want?

“As the production of software passes into the hands of software itself, coding agents are increasingly commissioned to build ag…”

나온 때 2026-10-08

가져온 때 2026-10-13 23:01 UTC · cc4e0966638e62f2

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
긴 작업 과정을 수행하는 터미널 에이전트용 데이터 확대

133 추천1 댓글

저자 9명한계 언급 없음

우리가 본 것

원제 — Scaling Agentic Data for Long-Horizon Terminal Intelligence

“Terminal agents are moving beyond local operations toward completing real-world professional tasks. Short trajectories can demo…”

대상 주장 — We achieve substantial performance gains on all 12 benchmarks spanning coding-agent tasks, agentic tasks in real-world production settings, and general reasoning.

나온 때 2026-10-08

가져온 때 2026-10-13 23:01 UTC · 5ca7f2d4afa12535

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
명령을 무시하고 계속 생각하는 인공지능 모델

215 추천2 댓글

저자 5명한계 적음

우리가 본 것

원제 — Thinking Inertia: LLMs Keep Thinking When Told Not To

“Large Language Models (LLMs) increasingly ship with explicit "thinking modes", yet their counterpart, "no-thinking", has receiv…”

나온 때 2026-10-07

가져온 때 2026-10-13 23:01 UTC · 611e236bfc72dfb4

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
사용자가 영상 흐름을 직접 조절하는 기술 연구

78 추천1 댓글

저자 13명한계 언급 없음

우리가 본 것

원제 — VIS-Ground: Video Interactive Storytelling with Contextual Grounding

“Video interactive storytelling enables viewers to actively steer how a video unfolds. However, once we allow viewers to interve…”

대상 주장 — Across three video generation backbones, VIS-Ground consistently achieves the highest overall composite score, reaching an average absolute improvement of 10.3 points over the strongest p…

나온 때 2026-10-06

가져온 때 2026-10-13 23:01 UTC · 00f2425bd978c006

뜯은 자리 — 초록

토론 ↗
출처 HF Daily Papers
물체를 정확히 찾아내는 AI 모델 GroundingPI 공개

247 추천1 댓글

저자 26명한계 언급 없음

우리가 본 것

원제 — GroundingPI: A Grounding Foundation Model towards Physical Intelligence with Visual Primitives

“Precise grounding matters. It specifies which object is the target and where that object is, even in clutter and for tiny objec…”

대상 주장 — Against 44 baselines across 34 grounding benchmarks spanning 11 perceptual capabilities, GroundingPI establishes a new state of the art, averaging 73.68%, above the larger GPT-6 Astra (71…

나온 때 2026-09-29

가져온 때 2026-10-13 23:01 UTC · 0c3dcf5d1875e3cc

뜯은 자리 — 초록

토론 ↗

논문·레포·모델·블로그·레딧·팟캐스트를 하루 한 번 기계가 긁는다. 모은 것은 한 번씩 뜯는다 — README·초록·모델 카드를 열어 보고, 거기서 나온 것은 카드가 되든 안 되든 계속 갖고 있는다. 제목과 링크는 원문으로 가고, 여기서 원문을 다시 싣지 않는다.

카드의 회색 줄은 소스가 내세우는 말이 아니라 뜯어서 나온 것이다 — 라이선스, 마지막 커밋, 무엇 위에 얹은 모델인지, 논문이 자기 한계를 적었는지. 무엇을 읽고 그렇게 적었는지는 「우리가 본 것」을 펴면 나온다. 「목록뿐」이라고 적힌 것은 원문을 못 읽었다는 뜻이다 — 우리를 막는 사이트가 있고, 그걸 읽은 척하지 않는다.

따옴표가 붙은 줄은 원문에서 그대로 옮긴 문장이다 — 대상이 스스로 밝힌 수치이지 우리가 잰 값이 아니다. 검증하지 않고 옮기기만 했고, 그러라고 따옴표를 붙였다.

한국어 제목과 요약은 기계(내 컴퓨터에서 돌리는 AI 모델)가 원문을 읽고, 처음 보는 사람도 알아듣게 풀어 쓴 것이다. 내가 읽고 쓴 것이 아니다. 원문에 없는 수치나 평가는 넣지 말라고 시켜 두었지만 기계가 쓴 것이니, 확실히 하려면 원문을 본다 — 원제는 카드를 펼치면 있다.

주제는 원문 제목·인용·태그에 나온 낱말을 정해진 목록과 맞춰 기계가 매긴 것이다 — 카드를 읽는 모델은 없다. 아무 낱말도 안 걸려 주제가 하나도 없는 카드가 있고, 주제를 고르면 그건 빠진다. 소스와 주제는 같이 걸린다.

카드마다 그때 실제로 읽은 문장 한 줄과, 그때 받아 온 응답의 지문을 남긴다. 원문은 여기 저장하지 않는다 — 나중에 원문이 바뀌거나 사라져도 담보하는 것은 "우리가 본 시점의 그 문장"이지 페이지 전체가 아니다.