05

오늘의 AI 소식

12쪽 중 2쪽

지난 카드를 글로만 보관한 쪽이다. 그림과 짧은 요약은 첫 쪽에 있는 동안만 남고, 제목을 누르면 어느 쪽이든 원문으로 간다.

출처 AWS ML Blog새로 나옴
How MoEngage turned over 400 APIs into agent tools with AgentCore Gateway

10월 29일

한계 적음2.7k단어

우리가 본 것

“MoEngage turned roughly 400 private REST APIs across 7 AWS Regions into permission-scoped agent tools with Amazon Bedrock Agent…”

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · b6409102d5fb4221

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 AWS ML Blog새로 나옴
Accelerate agentic AI with NVIDIA Nemotron models on Amazon EKS and SageMaker HyperPod EKS

10월 29일

한계 적음1.5k단어

우리가 본 것

“NVIDIA Nemotron 3.5 Super VL is a 120B-parameter mixture-of-experts model that pairs reasoning and tool use with multimodal und…”

대상 주장 — Sparse routing activates 12B of the 120B parameters per token, so compute per token matches a much smaller model while GPU memory still holds the full weights.

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · e66561f07afb6125

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 Hugging Face Blog새로 나옴
Granite Switch 4.1.1 — Update models like you update software

10월 29일

한계 언급 없음387단어

우리가 본 것

제목과 링크만 주는 소스라 인용할 것이 없다.

대상 주장 — The version number means what it means in software: fully backwards compatible with 4.1, no migration, incremental improvements under the hood.

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · 2991e858c7dcc01d

뜯은 자리 — 원문 페이지

Distribution Matching Distillationscore differences출처 HF Daily Papers
Intrinsic Distribution Matching

161 추천2 댓글

Distribution Matching Distillation저자 10명한계 언급 없음

우리가 본 것

“Intrinsic Distribution Matching improves few-step text-to-image generation by adding explicit moment constraints to distributio…”

대상 주장 — At two network evaluations, IDM reaches 94.25% and 90.20% on Chinese and English LongText-Bench, the highest scores among the compared methods at this budget.

나온 때 2026-10-28

가져온 때 2026-10-30 08:31 UTC · ab35c0065c0d7180

뜯은 자리 — 초록

토론 ↗
vision-language modelsimplicit user intent출처 HF Daily Papers
StreamVibe: Proactive Video Agents for Evolving User Intent

239 추천1 댓글

vision-language models저자 16명한계 적음

우리가 본 것

“StreamVibe introduces a benchmark, streaming vision-language model, and hierarchical memory harness to enable proactive, intent…”

대상 주장 — Our experiments reveal three key findings: (i) StreamVibe-VL preserves strong general video understanding while improving response timing and answer quality by 10.7% over other baselines;…

나온 때 2026-10-25

가져온 때 2026-10-27 23:01 UTC · 723fbc9b05bc2768

뜯은 자리 — 초록

토론 ↗
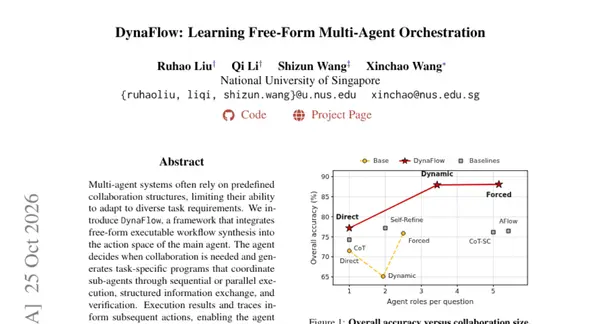
multi-agent systemsexecutable workflow synthesis출처 HF Daily Papers
DynaFlow: Learning Free-Form Multi-Agent Orchestration

183 추천1 댓글

multi-agent systems저자 4명한계 언급 없음

우리가 본 것

“DynaFlow enables adaptive multi-agent collaboration by letting a main agent synthesize executable workflows that coordinate sub…”

대상 주장 — Across six benchmarks spanning mathematical reasoning, scientific question answering, and multi-hop retrieval, DynaFlow achieves 88.08% overall accuracy in Forced mode, outperforming the …

나온 때 2026-10-24

가져온 때 2026-10-27 23:01 UTC · 7a36cfe1ae735348

뜯은 자리 — 초록

토론 ↗
spatial VLMinterface lock-in출처 HF Daily Papers
ChronoReplay: One Answer Interface Is Not Enough for Streaming Spatial Intelligence

344 추천1 댓글

spatial VLM저자 11명한계 적음

우리가 본 것

“ChronoReplay mitigates interface lock-in in spatial vision-language models by replaying heterogeneous spatial supervision chron…”

대상 주장 — Under the same observation access, a single ChronoReplay checkpoint improves OVO-S-Bench, OST-Bench, and UCS-Bench together, including a 13.41-point gain on OST-Bench, and achieves the hi…

나온 때 2026-10-24

가져온 때 2026-10-28 23:01 UTC · 3e23f390d50d9f9d

뜯은 자리 — 초록

토론 ↗
compositional coveragedecision grounding출처 HF Daily Papers
Trajectory2Gym: Decision-Grounded Compositional Interaction Synthesis for Tool-Use Agents

331 추천2 댓글

compositional coverage저자 8명한계 언급 없음

우리가 본 것

“Trajectory2Gym improves tool-use training by constructing interactions with compositional coverage and decision grounding rathe…”

대상 주장 — Across five Qwen3 scales, Trajectory2Gym improves Tau1, Tau2, and BFCL at every tested scale, increasing the equal-weight three-benchmark mean by 16.9-29.8 percentage points.

나온 때 2026-10-23

가져온 때 2026-10-27 23:01 UTC · f3e560bb6efc53f2

뜯은 자리 — 초록

토론 ↗
agent harnessesTraceTrial-Bench출처 HF Daily Papers
Trial by Trace: Benchmarking AI Agent Harnesses for Reliability and Failure Attribution

215 추천4 댓글

agent harnesses저자 23명한계 언급 없음

우리가 본 것

“TraceTrial-Bench evaluates agent harness reliability across seven components using mechanism-oriented tasks, trajectory tracing…”

대상 주장 — Across 4 harnesses, 9 models, and 95 tasks, our evaluation of 3,420 runs yields macro-averaged harness scores ranging from 59.8% to 72.0%, while 31.1% of runs achieve task success despite…

나온 때 2026-10-22

가져온 때 2026-10-27 23:01 UTC · 0407396b8ed5b422

뜯은 자리 — 초록

토론 ↗
translationtransformers출처 Hugging Face
tencent/Hy-SimulMT-30B-A3B-FP8

338 좋아요165 다운로드

apache-2.0

우리가 본 것

제목과 링크만 주는 소스라 인용할 것이 없다.

대상 주장 — In our RealSI long-form audio evaluation, Hy-SimulMT achieved a StreamLAAL of approximately 3 seconds, the lowest among the systems shown in the comparison.

나온 때 2026-10-22

가져온 때 2026-10-28 23:01 UTC · 5e7782b7b74485de

뜯은 자리 — 모델 카드

C출처 GitHub
impacifist/Windows-GPU-UNLOCK

1.3k 스타124 포크

GPL-2.0C커밋 오늘

국가 추정 · 한국

우리가 본 것

“Windows GPU UNLOCK: RTX3090 UEFI port, Korean no-reset Windows boot guide, verified source and benchmark evidence”

대상 주장 — X870, B660-PLUS and H610M are not wired into Configure.

나온 때 2026-10-20

가져온 때 2026-10-30 08:31 UTC · b099ec240bc74ade

계정이 적어 둔 문자열 — South Korea

뜯은 자리 — README

출처 Simon Willison새로 나옴
API credits benefit for eligible ChatGPT subscriptions

10월 29일

한계 언급 없음

우리가 본 것

“API credits benefit for eligible ChatGPT subscriptions Earlier this month Anthropic announced a generous new benefit for their …”

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · d462d95895c56a4f

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 TechCrunch AI새로 나옴
As search traffic dries up, Reddit announces it’s shifting to a logged-in experience

10월 29일

한계 언급 없음1.1k단어

우리가 본 것

“As AI transforms how people find information online, Reddit is rethinking its open-web roots to protect its audience and business.”

대상 주장 — Get your pass and bring someone with you at 50% off.

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · a096f053182d26fb

뜯은 자리 — 원문 페이지

출처 TechCrunch AI새로 나옴
Rivian expands joint venture with VW to include AI assistant

10월 29일

한계 언급 없음919단어

우리가 본 것

“Rivian doesn't disclose if the value of its $5.8 billion joint venture will expand as a result.”

대상 주장 — Get your pass and bring someone with you at 50% off.

나온 때 2026-10-29

가져온 때 2026-10-29 23:01 UTC · 321b98b0413d3f27

뜯은 자리 — 원문 페이지

출처 Latent Space
How Anthropic ships the #1 LLM in the World safely: Separating the Brain from the Hands

10월 27일

한계 언급 없음

우리가 본 것

“Katelyn Lesse and Angela Jiang join Latent Space to explain the engineering behind the Claude Platform: launching Opus 5.5, sep…”

대상 주장 — Katelyn Lesse and Angela Jiang join Latent Space to explain the engineering behind the Claude Platform: launching Opus 5.5, separating the model’s “brain” from the ag…

나온 때 2026-10-27

가져온 때 2026-10-27 23:01 UTC · 7cab449509941e06

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 Hacker News
The Exponential Time Hypothesis Is False [pdf]

774 점280 댓글

한계 언급 없음

우리가 본 것

“See also: <i>Announcing three new discoveries in mathematics, computer science, and physics</i> - <a href="https:&#x2F;&#x2F;ne…”

대상 주장 — See also: Announcing three new discoveries in mathematics, computer science, and physics - https:&#x2F;&#x2F;news.

나온 때 2026-10-26

가져온 때 2026-10-27 23:01 UTC · 453ea16a5158f9c5

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

토론 ↗
video world modeldiffusion backbone출처 HF Daily Papers
Hy-Nomas: Towards Free-form Interactive World Generation

122 추천2 댓글

video world model저자 38명한계 언급 없음

우리가 본 것

“Hy-Nomas is a video world model that uses causal attention and structured conditioning to generate interactive, multi-turn vide…”

나온 때 2026-10-26

가져온 때 2026-10-28 23:01 UTC · ed5f2c71ab05e085

뜯은 자리 — 초록

토론 ↗
출처 r/LocalLLaMA
Anthropic의 오픈 웨이트 모델 무료 마케팅 사례

10월 12일

우리가 본 것

원제 — Once again anthropic doing free marketing for open weight models

“&#32; submitted by &#32; /u/kubblegum [link] &#32; [comments]”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 2df71c78f8c17eb2

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

토론 ↗
출처 r/LocalLLaMA
It's been 2 months

10월 12일

우리가 본 것

“&#32; submitted by &#32; /u/Comfortable-Rock-498 [link] &#32; [comments]”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 14974d810b203271

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

토론 ↗
출처 Hacker News
Codex CLI의 자동 업데이트 기능 안내

398 점217 댓글

한계 언급 없음161단어

우리가 본 것

원제 — Codex CLI installs a persistent, self-updating background daemon by default

제목과 링크만 주는 소스라 인용할 것이 없다.

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 8743b22147cae345

뜯은 자리 — 원문 페이지

토론 ↗
출처 Simon Willison
파이썬 3.15 출시와 주요 변경 사항 안내

10월 12일

한계 언급 없음919단어

우리가 본 것

원제 — Hello Python 3.15, goodbye 3.10, and now I can use 3.11

“Python 3.15 is here! Here's the essential What's new in Python 3.15 guide, this year curated by 3.14 and 3.15 release manager H…”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 64044568da6e2c6c

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 TechCrunch AI
Meta의 첫 번째 대규모 AI 모델 Muse Wonder 출시

10월 12일

한계 언급 없음

우리가 본 것

원제 — Meta releases its first frontier model, Muse Wonder

“Where Muse Spark aimed to be a lightweight model that could perform at low latency, the Wonder models are larger and said to be…”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · d114aa759cc7bec6

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 AWS ML Blog
아마존 베드록에서 오픈AI 모델 사용 가능

10월 12일

한계 언급 없음2.8k단어

우리가 본 것

원제 — Accessing OpenAI GPT models on Amazon Bedrock with global cross-Region inference in Thailand, Malaysia, Singapore, Indonesia, and Taiwan

“Learn how to run OpenAI GPT-6 Sol, Luna, and Astra on Amazon Bedrock through global cross-Region inference from Singapore, Jaka…”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · cd9c7afc09d255a5

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 Google DeepMind
질병의 발견과 치료를 돕는 기술 적용

10월 12일

한계 언급 없음3.0k단어

우리가 본 것

원제 — Applying technology to understand and treat disease

“In collaboration with scientists and research partners, Google is helping to make disease more detectable, treatable, and preve…”

대상 주장 — @keyframes gemini-draw-border-timeline{0%{--border-draw-percent:0%;--border-mask-color:transparent;--btn-bg-color:var(--btn-bg-start);--gradient-angle:var(--start-angle,145deg)}85%{--bord…

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 611b6aeecd885647

뜯은 자리 — 원문 페이지

출처 TechCrunch AI
WindBorne, 미국 공군과 날씨 데이터 공급 계약 체결

10월 12일

한계 언급 없음924단어

우리가 본 것

원제 — WindBorne wins a hefty US Air Force contract for its balloon data

“A Silicon Valley startup that uses weather balloons and AI to predict the weather won a U.S. military contract worth almost $50…”

대상 주장 — Get your pass and bring someone with you at 50% off.

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 302bdda88b25293e

뜯은 자리 — 원문 페이지

출처 r/LocalLLaMA
MiniCPM-V 4.7 최신 모델 공개

10월 12일

한계 언급 없음351단어

우리가 본 것

원제 — openbmb/MiniCPM-V-4.7-35B-A3B

“gguf&#39;s: https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B-gguf &quot;MiniCPM-V 4.7 is the latest model in the MiniCPM-V …”

대상 주장 — With our Lookahead Expert Scheduling (LES) technique introduced alongside MiniCPM-V 4.7, combined with fine-grained layer-wise quantization and DSpark speculative sampling integration, Mi…

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · 84c5de4431f8576e

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

토론 ↗
출처 Hacker News
Muse Wonder

482 점256 댓글

한계 언급 없음1.3k단어

우리가 본 것

제목과 링크만 주는 소스라 인용할 것이 없다.

대상 주장 — But given its in-distribution performance, Muse Wonder Full performs even better on unfamiliar tasks than the Muse Spark 1.3 trend would predict.

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · b31dee8e5c3dce7e

뜯은 자리 — 원문 페이지

토론 ↗
출처 AWS ML Blog
Amazon SageMaker AI에서 llama.cpp로 결정 모델 배포하기

10월 12일

한계 적음2.2k단어

우리가 본 것

원제 — Deploy decision models with llama.cpp on Amazon SageMaker AI

“Learn how to deploy decision models with llama.cpp on Amazon SageMaker AI. This technical how-to serves OpenAI-compatible chat …”

대상 주장 — 8xlarge, 32 threads llama-cpp:server-sagemaker-cpu-v1 231/231 179/231 (77.5%) 1.715 seconds 19.291 seconds Qwen3.5-4B Q4KM, ml.

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · ae2468b8fd36a230

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

출처 AWS ML Blog
레이(Ray) 컨테이너를 이용한 여러 대의 컴퓨터 작업 실행 방법

10월 12일

한계 적음2.3k단어

우리가 본 것

원제 — Run multi-node inference workloads using Ray LLM Deep Learning Containers

“Learn how to deploy one large language model across two GPU nodes on Amazon EKS using the multi-node Ray LLM Deep Learning Cont…”

나온 때 2026-10-12

가져온 때 2026-10-12 23:01 UTC · d2840f479e1f9b59

뜯은 자리 — 목록뿐 (원문을 못 읽었다)

논문·레포·모델·블로그·레딧·팟캐스트를 하루 한 번 기계가 긁는다. 모은 것은 한 번씩 뜯는다 — README·초록·모델 카드를 열어 보고, 거기서 나온 것은 카드가 되든 안 되든 계속 갖고 있는다. 제목과 링크는 원문으로 가고, 여기서 원문을 다시 싣지 않는다.

카드의 회색 줄은 소스가 내세우는 말이 아니라 뜯어서 나온 것이다 — 라이선스, 마지막 커밋, 무엇 위에 얹은 모델인지, 논문이 자기 한계를 적었는지. 무엇을 읽고 그렇게 적었는지는 「우리가 본 것」을 펴면 나온다. 「목록뿐」이라고 적힌 것은 원문을 못 읽었다는 뜻이다 — 우리를 막는 사이트가 있고, 그걸 읽은 척하지 않는다.

따옴표가 붙은 줄은 원문에서 그대로 옮긴 문장이다 — 대상이 스스로 밝힌 수치이지 우리가 잰 값이 아니다. 검증하지 않고 옮기기만 했고, 그러라고 따옴표를 붙였다.

한국어 제목과 요약은 기계(내 컴퓨터에서 돌리는 AI 모델)가 원문을 읽고, 처음 보는 사람도 알아듣게 풀어 쓴 것이다. 내가 읽고 쓴 것이 아니다. 원문에 없는 수치나 평가는 넣지 말라고 시켜 두었지만 기계가 쓴 것이니, 확실히 하려면 원문을 본다 — 원제는 카드를 펼치면 있다.

주제는 원문 제목·인용·태그에 나온 낱말을 정해진 목록과 맞춰 기계가 매긴 것이다 — 카드를 읽는 모델은 없다. 아무 낱말도 안 걸려 주제가 하나도 없는 카드가 있고, 주제를 고르면 그건 빠진다. 소스와 주제는 같이 걸린다.

카드마다 그때 실제로 읽은 문장 한 줄과, 그때 받아 온 응답의 지문을 남긴다. 원문은 여기 저장하지 않는다 — 나중에 원문이 바뀌거나 사라져도 담보하는 것은 "우리가 본 시점의 그 문장"이지 페이지 전체가 아니다.

계정이 스스로 적은 자유 문자열 하나로 추정한다. 절반은 그 칸을 비워 둔다 — 그래서 「미상」을 숨기지 않고 한 칸으로 둔다.